Running an AI model inside your own infrastructure does not automatically make it private. A local model can still leak confidential data through prompt logs, vector databases, poorly secured endpoints, telemetry, employee access, or an agent that quietly connects to the public internet.
That distinction matters for organizations investigating how to implement local ai models for enterprise privacy. The real objective is not merely moving inference away from a third-party API. It is controlling the entire path taken by sensitive information—from the employee’s prompt to retrieval systems, model memory, logs, storage, tools, and output.
For enterprises handling customer records, intellectual property, financial data, health information, or regulated workloads, local AI can substantially reduce exposure. But privacy comes from architecture and governance, not the location of the GPU.
Start With the Data, Not the Model
Before selecting GPUs or downloading model weights, classify what employees will actually send into the system. Create four practical categories: public information, internal business information, confidential information, and highly restricted or regulated information. Then map where each category is allowed to travel.
The Federal Trade Commission recommends minimizing the information businesses collect and retain because unnecessary data creates unnecessary security exposure.
Apply the same principle to AI. If a customer-service assistant needs order numbers and product details, it probably does not need unrestricted access to an entire customer database. The strongest privacy architecture begins by reducing what the model can see.
Choose the Right Local Inference Stack
Different runtimes solve different operational problems. Ollama and llama.cpp are practical for prototypes, developer environments, edge devices, and smaller controlled deployments. LM Studio and Jan can serve workstation-based use cases.
For centralized enterprise inference with concurrent users and higher throughput, platforms such as vLLM are generally better suited to GPU servers and production orchestration.
Model selection matters equally. A company may not need a massive reasoning model for every request. Smaller open-weight models can handle classification, summarization, extraction, routing, and structured data tasks while requiring substantially less memory.
Quantization can reduce hardware requirements further. INT8 and INT4 approaches compress model representations, although teams should benchmark accuracy because aggressive compression can affect output quality.
The right question is therefore not “What is the biggest model we can host?” It is “What is the smallest model that reliably completes this business task?”
Keep Retrieval Private Too
Many enterprise assistants rely on retrieval-augmented generation, or RAG. A user asks a question, the system searches internal documents, retrieves relevant passages, and provides those passages to the model as context.
Running the LLM locally while sending embeddings or documents to an external retrieval service defeats part of the privacy advantage.
Instead, organizations can host PostgreSQL with pgvector, another self-managed vector database, and a local embedding model inside the same controlled environment.
Permissions should carry through retrieval as well. An employee who cannot normally open payroll records should not suddenly retrieve payroll information simply because the AI interface can search the database.
This becomes particularly important as businesses expand from simple productivity software into the types of AI productivity tools for remote teams that touch multiple internal systems.
How to Implement Local AI Models for Enterprise Privacy: A Six-Layer Test
A useful deployment review can be reduced to six questions.
1. Can the Model Reach the Public Internet?
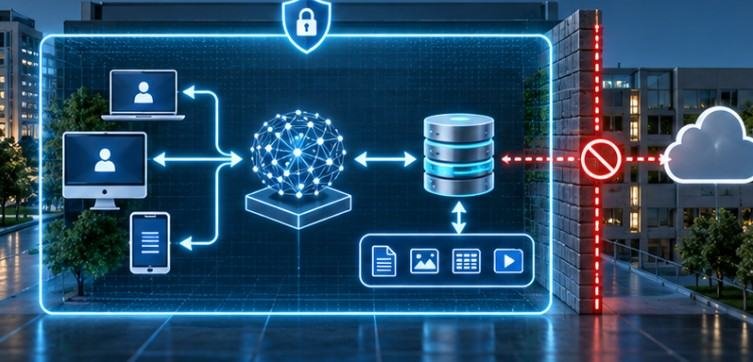
Place inference servers inside dedicated subnets or segmented networks and restrict unnecessary outbound connections. CISA describes microsegmentation as an important zero-trust technique because it can reduce attack surface and limit lateral movement if one component becomes compromised.
For especially sensitive systems, consider default-deny egress policies rather than merely trusting applications not to connect externally.
2. Who Can Query the Model?
Connect AI endpoints to enterprise identity systems and enforce role-based or attribute-based access. Authentication alone is insufficient. Authorization should determine which models, datasets, retrieval indexes, agents, and tools each user can access.
3. What Gets Logged?
Prompts frequently contain the most sensitive information in an AI deployment. Avoid retaining complete prompts and responses unless there is a defined security, troubleshooting, or regulatory reason. Where logging is necessary, apply PII detection, redaction, retention limits, encryption, and restricted access.
4. Is Sensitive Data Encrypted?
Protect model storage, document repositories, vector databases, backups, and audit logs at rest. Protect traffic between clients, gateways, retrieval systems, and inference servers in transit.
For healthcare organizations, HHS requires appropriate administrative, physical, and technical safeguards for electronic protected health information and specifically addresses access control, authentication, auditing, and transmission security.
Importantly, HIPAA does not prescribe one universal technology configuration. Security controls depend on risk assessment.
5. Can the AI Use Tools?
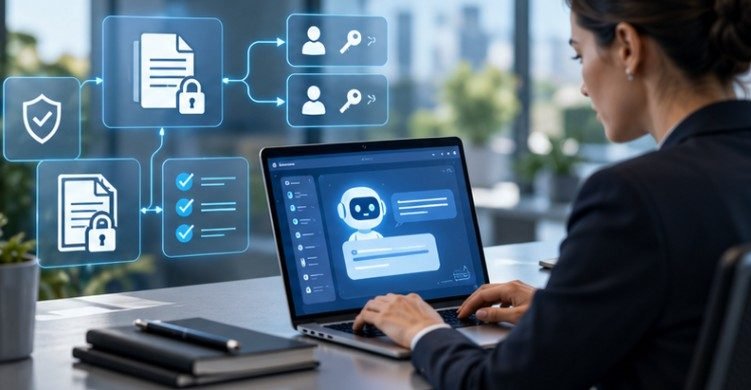
Tool access can create more risk than inference itself.
An isolated chatbot that summarizes text is very different from an agent that can query databases, send email, modify files, execute code, or call APIs.
Treat every tool as a privilege. Allow only specific actions, validate parameters, require approval for sensitive operations, and maintain audit trails.
OWASP’s current guidance for generative AI systems highlights risks extending beyond the underlying language model to the applications and agents surrounding it.
6. Can You Prove What Happened?
Privacy programs eventually encounter the same question: who accessed what? Maintain security-focused audit records covering authentication events, administrative changes, model versions, retrieval access, configuration changes, and permitted tool activity without unnecessarily storing confidential prompt content. That separation gives security teams visibility without turning the logging platform into another sensitive-data repository.
Add Confidential Computing Where the Threat Model Requires It
Highly sensitive organizations may need protection while information is actively being processed, not only while stored or transmitted.
Confidential-computing technologies can isolate workloads within hardware-protected environments. These architectures are relevant when organizations need stronger separation between workloads, infrastructure operators, and sensitive inference data.
They are not required for every deployment. The additional infrastructure complexity should be justified by an actual threat model rather than added simply because the technology exists.
Compliance Still Requires Governance
Local deployment does not mean “HIPAA compliant,” “SOC 2 compliant,” or “GDPR compliant” by default. HIPAA, for example, requires regulated organizations to assess risks and implement appropriate administrative, technical, and physical safeguards. HHS also expects controls such as authorized access and system activity review.
SOC 2 is an assurance and attestation framework rather than a privacy regulation, while GDPR can still affect US organizations processing covered EU personal data.
Technical controls therefore need supporting policies: model approval procedures, acceptable-use rules, employee training, incident response, retention schedules, vendor reviews, vulnerability management, and periodic risk assessments.
Even relatively low-risk implementations—such as internal marketing experiments or AI-powered SEO tools for beginners—should have boundaries around confidential customer and company data.
Frequently Asked Questions
1. Are local AI models completely private?
No. Privacy depends on networking, logging, storage, retrieval, user permissions, telemetry, integrations, and agent tools. A local model can still expose information through an insecure surrounding application.
2. Can a local LLM help with HIPAA compliance?
Yes, it can reduce certain third-party data exposures, but local hosting alone does not satisfy HIPAA. Organizations still need risk analysis, access controls, auditing, security procedures, and other appropriate safeguards.
3. Should enterprises disable internet access for local AI models?
For highly sensitive workloads, restricting unnecessary outbound connectivity can significantly reduce exposure. Some deployments still require controlled external services, so organizations should use allowlists and explicit egress policies based on business requirements.
4. Do enterprises need large models for private AI?
Usually not. Smaller task-specific models can perform extraction, classification, summarization, routing, and retrieval-assisted question answering efficiently while lowering GPU, latency, and infrastructure requirements.
Final Thoughts
The strongest argument for local AI is not that information physically stays inside one server room. It is that the enterprise gains control over where information travels, who can access it, how long it survives, and what software can act on it.
That control disappears if prompts are logged indefinitely, retrieval ignores permissions, agents have unrestricted tools, or inference servers can quietly communicate outside the network.
Organizations planning private AI should therefore start with one sensitive workflow, map every data movement, restrict access and egress, test the smallest suitable model, and audit the complete pipeline. Local inference becomes genuinely private only when the architecture around the model is private too.